1 Evolution of Computers
Computer Performance
Clock speed (f ): cycles per second,
measured in Hz.
Average CPI:
i
CPI
i
×I
i
i
I
i
Process Time (T ):
(
i
I
i
)×CP I
f
MIPS:
f
CPI×10
6
2 Digital Logic
Boolean Algebra
A ⊕ B = AB + AB
A ⊕ B = AB + AB
Algebra Laws
A + 0 = A A · 1 = A Identity Elements
A + 1 = 1 A · 0 = 0 Null Law
A + A = A A · A = A Idempotent Law
A + A = 1 A · A = 0 Inverse
(A + B) + C = A + (B + C) Associative (1)
(A · B) · C = A · (B · C) (2)
A · (B + C) = A · B + A · C Distributive (1)
A + (B · C) = (A + B) · (A + C) (2)
De Morgan’s Theorem
A · B · · ·· · N = A + B + ·· · + N
A + B + · ·· + N = A · B · ·· · · N
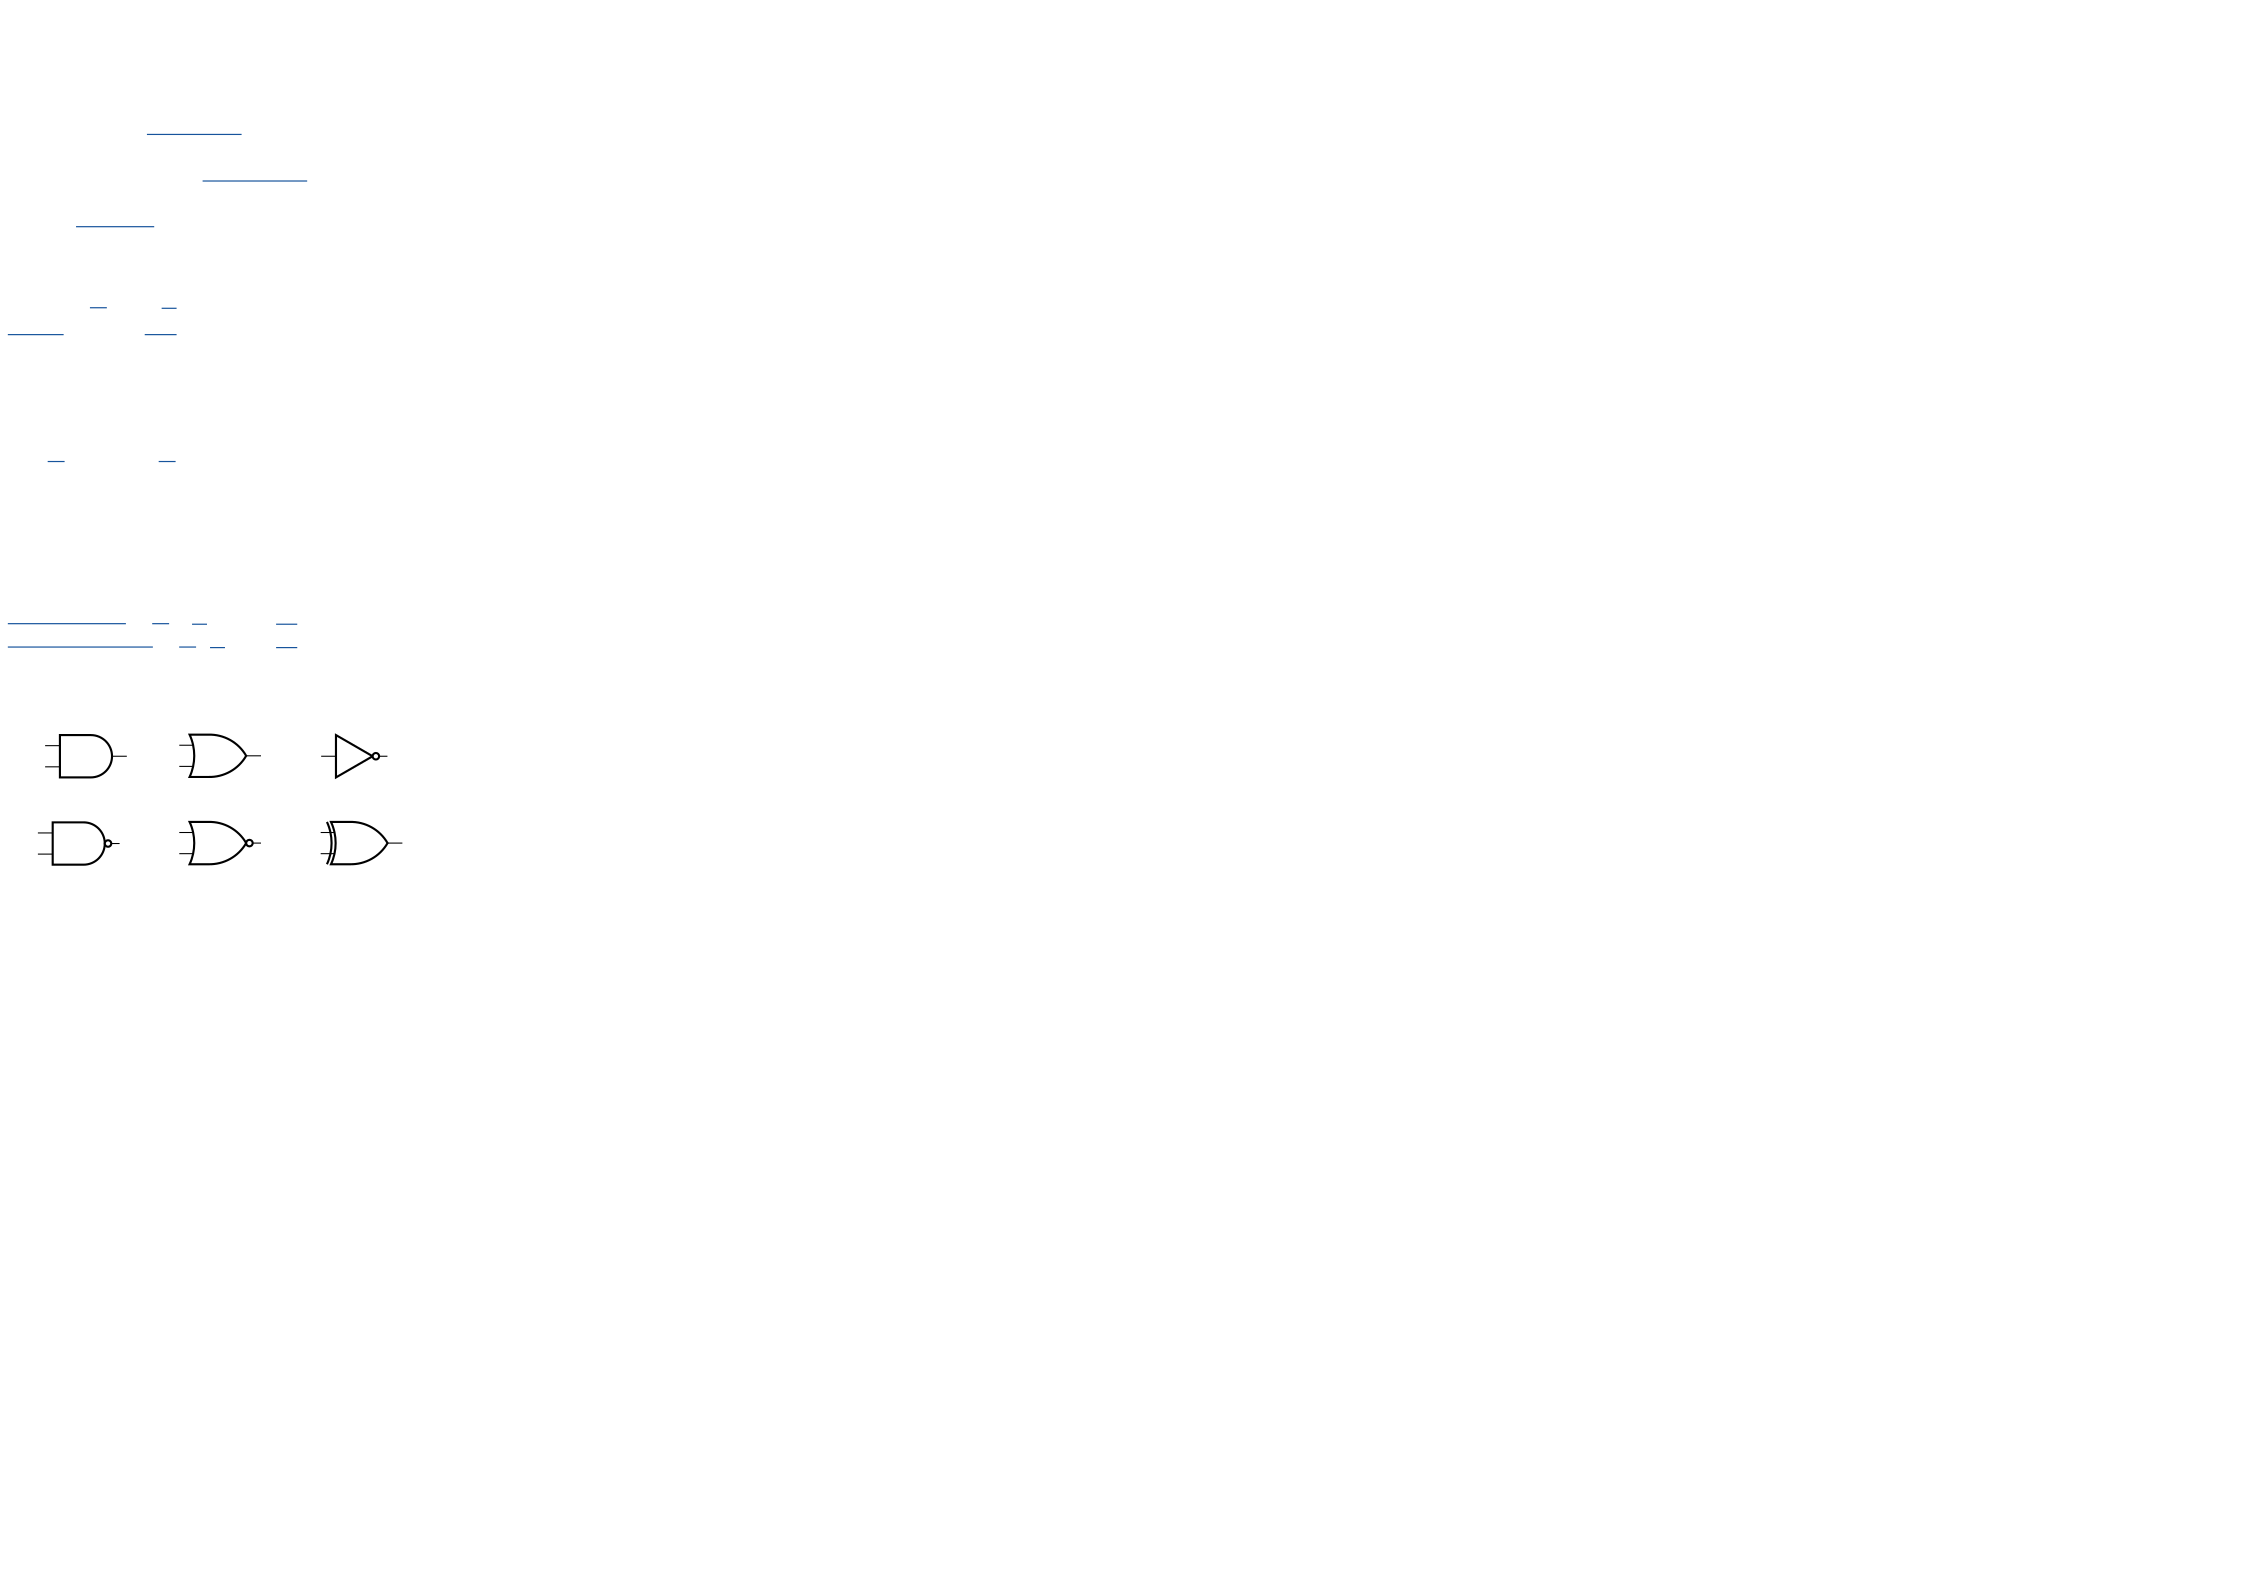
Logic Gates
AND OR NOT
NAND NOR XOR
Functional Complete Set
Any boolean function can be
implemented by the set.
{AND, OR, NOT} {NAND} {NOR}
{AND, NOT} {OR, NOT}
Implementing Functions
SOP: (1) write 1’s as minterms (products
of variables), (2) sum minterms.
POS: (1) write 1’s as product terms of
variables, (2) apply NOT to each term,
(3) apply De Morgan’s, (4) connect terms
with AND.
Karnaugh Map: (1) write map,
rows/columns differ by only 1 bit,
(2) circle 1’s as large, in powers of 2,
rectangular, wrap if needed (3) each
group is a product, sum groups.
Adders
Half Adder: S = A ⊕ B C = A · B
Full Adder: S = A ⊕ B ⊕ C
in
C
out
= A · B + C
in
· (A ⊕ B)
3 Number Representation
Positional Number System
i
(a
i
r
i
) Direct (O(n
2
))
r(r(a
n
+ a
n−1
) + ·· ·) + a
0
Iterative (O(n))
Binary Integers
uint:
n−1
i=0
2
i
a
i
Sign-Mag: (−1)
a
n−1
n−2
i=0
2
i
a
i
1’s Comp: (if < 0) bit-wise NOT
2’s Comp: (if < 0) 1’s Comp + 1
−2
n−1
+
n−2
i=0
2
i
a
i
MSB of 1’s Comp and 2’s Comp is sign
bit.
Binary Integer Arithmetics
Negation of 2’s Comp
Take 2’s Comp of the 2’s Comp.
Add/Sub of 2’s Comp
Add/Sub directly.
Overflow: Two numbers of same sign
added to get oppposite sign.
Multiplication (multiplicand × multiplier)
+ve×+ve: (1) for each multiplier bit,
(2) if 1, shift multiplicand left, add to
partial sum, (3) if 0, do nothing,
(4) return sum. Other cases: (1) for each
non-sign multiplier bit, (2) if 1, shift
multiplicand left, add to partial sum,
(3) if 0, do nothing, (4) for sign bit, if 1,
negate multiplicand, left shift, sign
extend, add to partial sum, (5) return
sum.
Excess-K
Values range: [0 − K, 2
n
− 1 − K]
K is typically chosen to be 2
n−1
− 1.
Floating Point Numbers
±Significand × 2
±(Biased) Exponent
Single: 32 bits, 8 exp, 23 sig.
Double: 64 bits, 11 exp, 52 sig.
Extended: 80 bits, 15 exp, 112 sig.
Special Values (used only when specified)
0: exp = 0, sig = 0.
Subnormalized: exp = 0, sig , 0.
∞: exp = all 1, sig = 0.
NaN: exp = all 1, sig , 0.
Properties
# of representable numbers same as int.
Not uniformly distributed.
Arithmetic laws not always hold.
Floating Point Arithmetics
Add/Sub
(1) Check 0. (2) Align significand
(smaller exp shift right). (3) Add/Sub
significands. (4) Normalise. (5) Round.
Multiplication/Division
(1) Check 0. (2) Multiply/Divide
significands. (3) Multiplication: add
exponents, sub K; Division: sub
exponents, add K. (4) Determine sign.
(5) Normalise. (6) Round.
Rounding Methods
Round to nearest even.
Round towards zero.
Round towards ±∞.
4 Instruction Execution Cycle
(1) Instruction address calculation;
(2) Instruction fetch; (3) Instruction
decode; (4) Operand address calculation;
(5) Operand fetch (one or more); (6) Data
operation; (7) Operand address
calculation; (8) Operand store;
(9) Interrupt check.
Operation Format
One word: [opcode, src1, src2,
dest] (register)
Two word: [opcode, src, address
model, dest], [address (mem)]
Instruction Fetch
(1) MAR ← PC; (2) PC ← PC + 1;
(3) MDR ← Mem[MAR]; PC increment
is implied, will change if branch.
Operand Fetch
Operands in registers: ALU ← Reg
Operands in memory: (1) MAR ← MBR;
(2) MBR ← Mem[MAR];
Interrupt Handling
Reasons: (1) Improve efficiency;
(2) Prevent data loss (e.g. from network);
(3) Other programs need to run (e.g.
time-sharing).
Information saved: (1) PC; (2) Modified
registers; (3) Flags; (4) Current
instruction address.
5 Memory
Memory Hierarchy: Inbound (Registers,
on-chip cache, cache, main mem) →
Outbound (disk, SSD, DVD) → Off-line
(magnetic tape)
Trends (top to bottom): Capacity ↑; Cost
per bit ↓; Access time ↑; Frequency of
access ↓.
Principle of Locality: Temporal (recently
accessed likely to be accessed again, e.g.
sum) and Spatial (items with nearby
addresses likely to be accessed soon, e.g.
arr[]).
Memory Organisation: Big Endian
(left-to-right) and Little Endian
(right-to-left).
Access Modes: Sequential, Random,
Associative.
Internal Memory
ROM: Read-only; Non-volatile; Written
by masks; No erasure.
PROM: Read-only; Non-volatile; Written
electrically; No erasure.
EPROM: Read-mostly; Non-volatile;
Written electrically; Erased by UV light.
EEPROM: Read-mostly; Non-volatile;
Written electrically; Erased electrically
(byte-wise).
Flash: Read-mostly; Non-volatile;
Written electrically; Erased electrically
(block-wise); limited write cycles.
DRAM: Read-write; Volatile; Use
transistors; Refresh needed; Slow;
Cheaper.
SRAM: Read-write; Volatile; Use logic
gates; No refresh; Fast; Expensive.
Bench-marking Memory Performance
Access Time: Time to read/write data.
Bandwidth/Transfer Rate: Rate at which
data can be read/written.
Memory Cycle Time: Access time +
Transfer time.
Cache Memory
A unit-addressable main memory with
n-bit addresses, a block size of 2
k
units,
has M = 2
n−k
blocks. The cache has m
blocks (lines), m ≪ M.
Address Mapping
Direct Mapping: 1-to-1 mapping.
(Cache line) = (Main mem block)%m.
Fields: Tag (remaining bits), Line (
r
bits,
corresponds to 2
r
lines), Offset (k bits,
corresponds to line size 2
k
addressable
units)
Pros: (1) Simple circuitry. (2) Fast.
Cons: (1) High miss rate.
Fully Associative: 1-to-all mapping.
Fields: Tag (remaining bits), Offset (k
bits, corresponds to line size 2
k
addressable units)
Pros: (1) Low miss rate. (2) Flexible use
of cache.
Cons: (1) Need to search all lines.
(2) Complex circuitry.
Set Associative: 1-to-some mapping.
m(# of lines) = v sets × k lines/set.
i (Set #) = j (Main mem block)%v.
Implementation: (1) v associative
caches. (high associativity) (2) k direct
cache. (k-way set associative, low
associativity)
Fields: Tag (remaining bits), Set (s bits,
corresponds to
v
= 2
s
sets), Offset (
k
bits,
corresponds to line size 2
k
addressable
units)
Pros: (1) Low miss rate.
Cons: (1) Complex circuitry.
Replacement Algorithms
Random: Randomly choose a line to
replace. (Not used)
FIFO: Replace the line that has been in
the cache the longest.
LRU: Replace the line that has been least
recently used.
LFU: Replace the line that has been least
frequently used.
Not applicable to direct mapping.
Write Policies
Write-through: Write every time cache is
changed.
Write-back: Write only when line is
replaced.
Performance
Average Access Time
= Hit time + Miss rate × Miss penalty.
Unified/Split Cache
Unified: Instructions and data share the
same cache. Auto balanced. Memory
contention problem on pipeline and
parallel executions, causes bottoleneck.
Split: Instructions and data have
fixed-size separate caches. Better
performance. Main trend.
Virtual Memory
Physical vs Logical Address: Physical for
addressing actual memory, space
smaller; logical visible to the program,
space may be larger.
Memory Management Unit (MMU): Maps
between logical and physical addresses.
Paging
Page vs Frame: Page is a fixed-size block
of logical memory, frame is a fixed-size
block of physical memory.
Demand Paging: Pages are loaded into
memory only when needed.
Page Fault: Occurs when a page is not in
memory.
Pros: fast response; less memory usage;
Cons: page faults until stable set of
pages loaded.
Page Table: One page table per process,
maps logical pages to physical frames.
PTE: (VPDF) – Valid bit (whether page
in memory), Protection bits (manages
access rights), Dirty bit (whether page
modified), Frame number (physical
frame #).
Translation Lookaside Buer (TLB): Like
a cache, stores some valid PTEs. TLB
consulted first, if not found, page table
is consulted.
External Memory
Hard Disk Drive (HDD)
Components: Platter (disk), Track
(concentric circle), Sector (segment of
track, 512 bytes), Cylinder (set of same
tracks vertically).
Sector Format: e.g. Gap 1 (separate
sectors) - ID Field (synch, track, head,
sector #, CRC) - Gap 2 (separate ID &
data) - Data Field (data, CRC) - Gap 3
Disk Layout Methods: (1) Constant
Angular Velocity - easy read/write,
density decreases towards the rim,
wastes space; (2) Multiple Zone
Recording - zones with different # of
sectors, maximise storage capacity,
density similar but NOT uniform
Data Access Time: (1) Seek time - move
read/write head to cylinder, distance
dependent, 5 - 15 ms startup, 0.2 - 1 ms
consecutive; (2) Rotational latency -
average is half a revolution; (3) Transfer
time - t
T
≪ seek + latency